AI
Who Else Learns From Your Data? What Distributors Should Ask Every AI Vendor
As distributors adopt AI for quoting, order entry and other workflows, they need to know exactly how vendors are using their data. This piece explains the risks of cross-customer AI training and outlines the questions distributors should ask to protect proprietary knowledge, customer information and years of accumulated expertise.
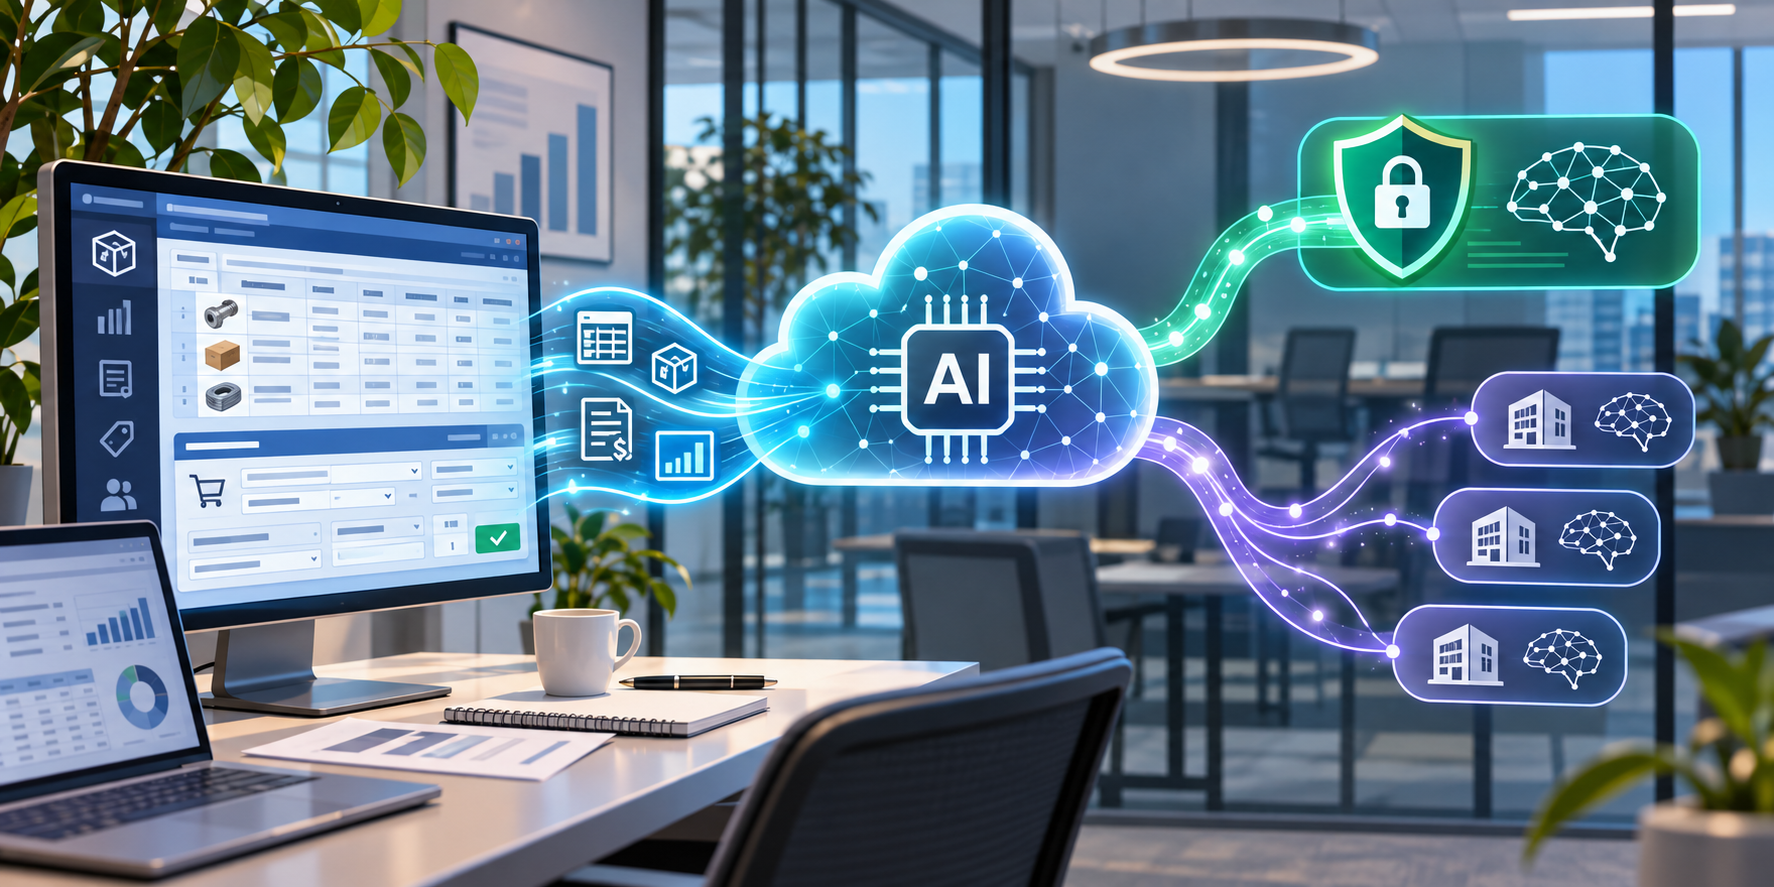
Distributor data is complex. It’s one thing to reconcile sales orders, invoices and POs. It’s a whole other level of difficulty to handle the lines underneath them — every sales order line and purchase order line. Distributors buy and sell across hundreds of thousands of SKUs. Some items are stocked, and others are non-stock or special orders. Some products ship configured, like a valve with a specific actuator or wire cut to length. Then there’s unit of measure. A contractor buys 10 fittings, the supplier sells them in boxes of 50 and the ERP has to convert between the two on every single line.
All these variables make distributor data arguably the most complex data in supply chain. Manufacturers don’t have to contend with this level of complexity. They control the master data — it’s their own products, after all. A distributor has to reconcile master data from hundreds of suppliers with the way thousands of customers describe what they want. And customers almost never use the catalog’s words.
With all this complexity, it can be tempting for AI companies to take a shortcut: pool what they learn from every distributor customer into one shared model. I call this cross-customer data training.
Data is distributors’ most valuable resource
The same complexity that makes distributor data hard is what makes it so valuable. Every quote a rep has built, every substitution a counter salesperson has approved, every customer part number a branch has mapped to an SKU — none of that lives anywhere else. A competitor can’t buy it, and a general-purpose AI model can’t guess it.
The biggest distributors already know this. Grainger CEO D.G. Macpherson told investors in February that the company’s “core product and customer information assets” have “taken on even greater importance as AI accelerates.” NAW’s 2026 AI Adoption Index — a survey of 302 respondents across wholesale distribution — drew the same conclusion: as AI moves into ERP, inventory, pricing, customer and delivery workflows, “generic capability will matter less than fit with a distributor’s data, products and microvertical.”
The industry is still building the guardrails. In the same NAW survey, 68.1% of respondents ranked data quality and integration among their top three barriers to AI. Only 39.4% have completed a formal inventory of their data assets, and only 32.2% have a formal AI governance framework. That’s not a knock on anyone. It’s early days. But it means the questions you ask your AI vendor matter more than ever.
Cross-customer data training: what is it?
In layman’s terms: AI for quoting and order entry starts with product matching. A customer sends a BOM, an email or a spreadsheet and the AI matches each line to an SKU in the distributor’s catalog. When a rep confirms the match, the system records a golden pair — this customer’s description paired with this SKU. Golden pairs teach the AI how a customer talks and what they actually mean.
With cross-customer data training, the AI company pools anonymized golden pairs from all of its distributor customers into one shared model. More customers means more repetition, a better history of golden pairs across a broader array of possibilities, and match rates that climb faster for everyone on the platform. Each new customer gets a head start built on what earlier customers taught the model.
That head start comes from somewhere. It comes from every distributor on the platform, including you.
Your contract with an AI vendor determines how broadly your data can be utilized. A June analysis from the law firm Morgan Lewis put it well: “the critical issue is often not who owns the underlying data but what rights the vendor receives.” You can own every record and still give the vendor the right to learn from all of it. Those rights can outlast the contract, and a model trained on your history doesn’t forget it when you cancel.
The easy way and the hard way
Pooling is the easy way out. The hard way is to give every distributor its own tenant, where the AI learns only from that distributor’s data, period. The vendor gives up the head start, so it has to put a lot more engineering into each customer to reach the same match rates. That’s harder for the vendor and better for the distributor, because every lesson your data teaches stays with you.
So ask your vendor how they are going to protect your data, and get the answer documented in your contract.
Your data is more than the final order
Every AI-assisted order creates four records:
- The customer’s original request — the BOM, the email, whatever came in.
- The AI’s first suggestion to the rep.
- The rep’s corrections to that suggestion.
- The final SKUs entered into the ERP.
Record 4 lands in your ERP, so you always have it. But records 1 through 3 hold the most valuable data in the transaction. The corrections show exactly where the AI got it wrong and how your best people fixed it. That’s years of product knowledge from your reps. That’s tribal knowledge.
Distributors are only as strong as their data, and your data includes all four records, not just the last one. Make sure you can get all four, in a format you can export, for every transaction.
What to look for in your AI agreements
Read your agreements with AI providers before you renew, and get answers in writing:
- Is there language in the agreement about “ecosystem data” or “generalized learning” from data? Ask exactly what each phrase lets the vendor do.
- Does the agreement explicitly say the AI provider won’t use your data to train its own shared knowledge or models?
- Is your company its own tenant, with a model that learns only from your data?
- Do you own the AI’s suggestions and your reps’ corrections — and can you export them?
If a vendor won’t answer these in writing, you have your answer.
Distribution runs on trust
This industry operates on one thing: trust. Your customers trust you with what they buy, what they pay and how they describe the job. When you hand that history to an AI vendor, you’re extending that trust on their behalf. So before you sign, find out who else learns from your data.